|
Yusen Luo I am currently working as research intern at LiraLab and GLAMOR Lab @ USC, advised by Prof. Erdem Bıyık and Prof. Jesse Thomason, and Darrell Group @ UC Berkeley, advised by Prof. Trevor Darrell and Dr. Roei Herzig. I am very fortunate to work with Jesse Zhang and Abrar Anwar. I received my Master's degree in Computer Science from University of Southern California. Before that, I graduated with Bachelor's degree in Computer Science from Beijing Jiaotong University. 🚀 I am currently applying for PhD programs for Fall 2026. |

|
ResearchMy research focuses on enabling robots to efficiently learn and adapt to new tasks with minimal supervision. My goal is to develop generalist robots to achieve broad generalization and robust performance across diverse real-world tasks and environments. To achieve this, I am interested in exploring two key directions in my PhD research: 1. Scaling Robots with Generalist Priors: Leveraging off-domain sources to equip robots not only with semantic understanding but also physical dynamics through video prediction and world models, building broader initial capabilities for downstream real-world adaptation. 2. Efficient Post-Training for Real-World Adaptation: Developing efficient post-training and adaptation paradigms that allow robots to autonomously refine their behaviors through interaction, ensuring robust generalization and safety in unstructured real-world environments. * indicates equal contribution |


|
ReWiND: Language-Guided Rewards Teach Robot Policies without New Demonstrations
Jiahui Zhang*, Yusen Luo*, Abrar Anwar*, Sumedh A. Sontakke, Joseph J. Lim, Jesse Thomason, Erdem Bıyık, Jesse Zhang CoRL, 2025 (Oral Presentation) 🏆 Best Paper Award OOD Workshop @ RSS 2025 Best Paper Nominee RoboReps Workshop @ RSS 2025 arXiv / website ReWiND enables sample-efficient adaptation to new tasks by training a language-conditioned reward model and policy from a small set of demonstrations to learn new tasks without additional per-task demonstrations. We beat baselines by 2X in simulation and improve real-world pre-trained policies by 5X in just 1 hour. |
|
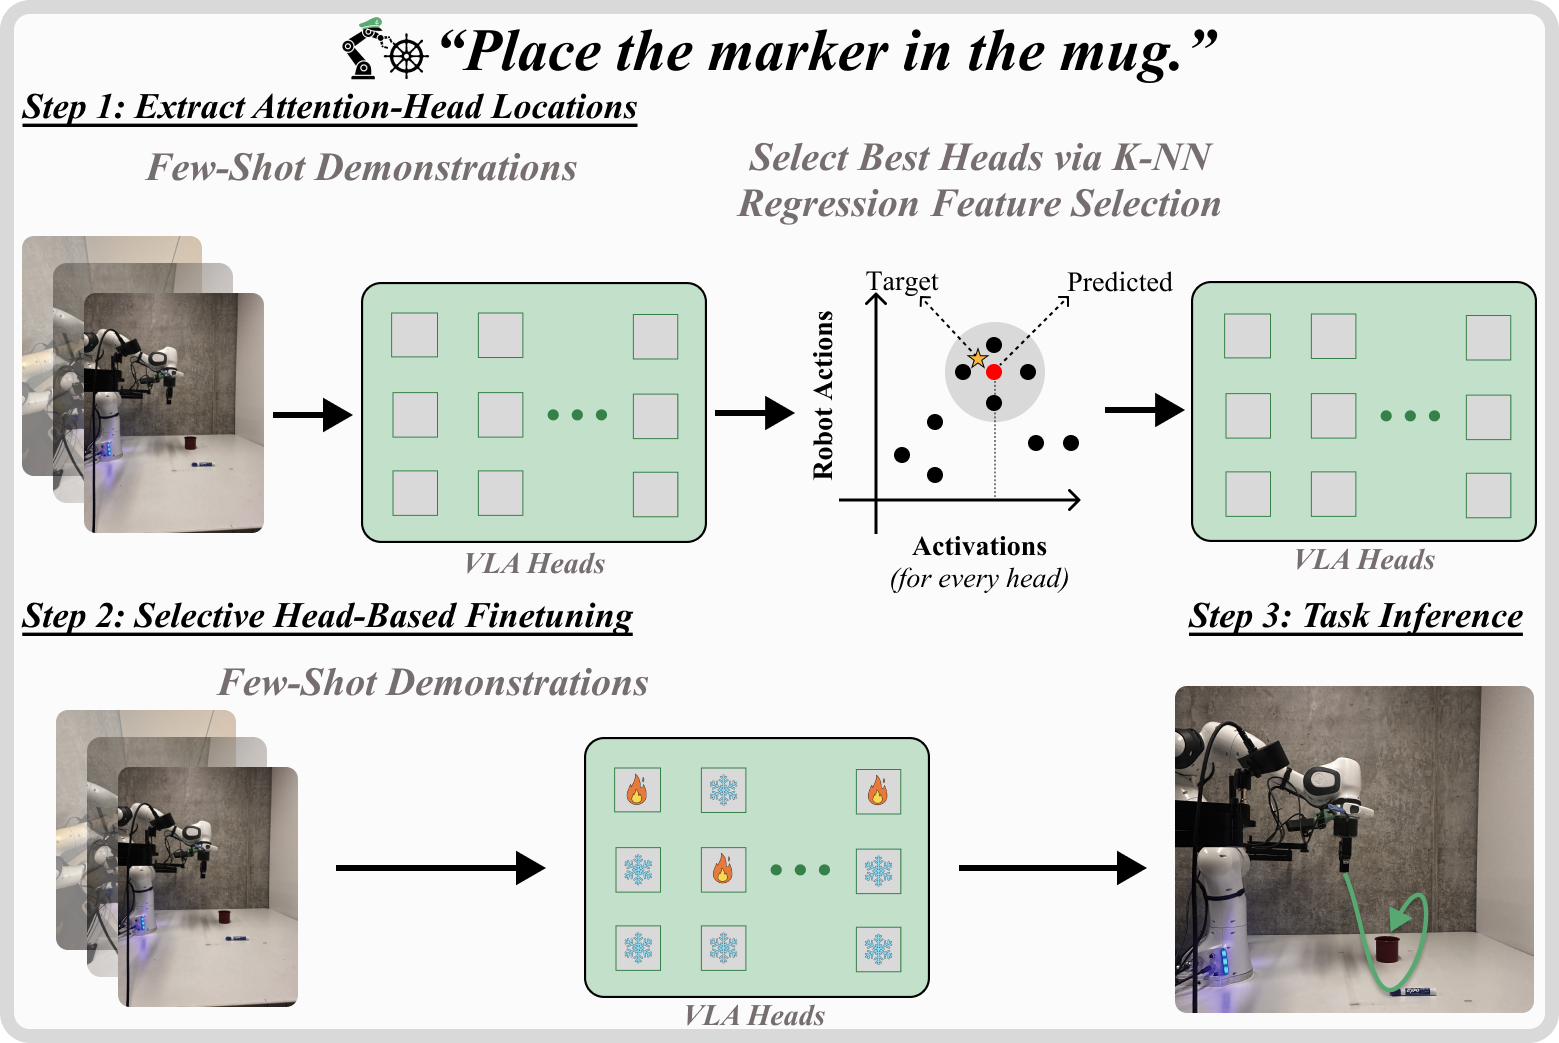
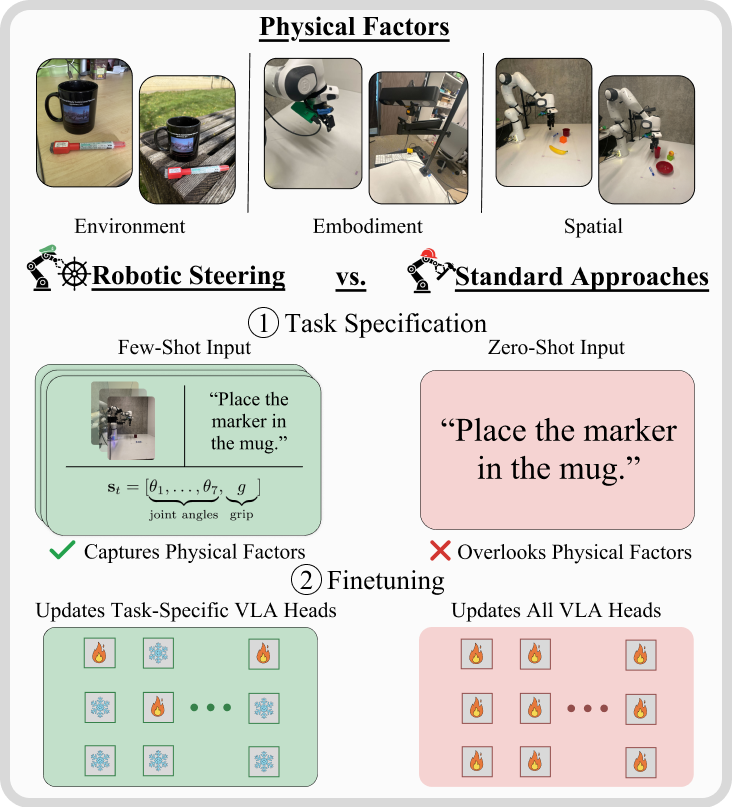
Robotic Steering: Mechanistic Finetuning of Vision-Language-Action Models via Few-Shot Demonstrations
Chancharik Mitra*, Yusen Luo*, Raj Saravanan*, Dantong Niu, Anirudh Pai, Jesse Thomason, Trevor Darrell, Abrar Anwar, Deva Ramanan, Roei Herzig In Submission, 2026 paper / arXiv / website We introduce Robotic Steering, a mechanistic fine-tuning framework for Vision-Language-Action (VLA) models. By analyzing internal activation patterns, our method selectively adapts only the attention heads critical for task-specific physical and semantic reasoning. Extensive real-world evaluations demonstrate that Robotic Steering achieves superior robustness and compute efficiency compared to standard LoRA (using 96% fewer trainable parameters). Crucially, it mitigates catastrophic forgetting and overfitting, preserving the model's generalist priors while enabling interpretable and reliable adaptation to diverse new tasks. |
|
Website template adapted from Jon Barron. |